You already know what a quantitative strategy is. What you do not have yet is the wiring diagram — the sequence that turns a hunch into software placing trades on rules you set, instead of you clicking a mouse and second-guessing every entry.
Discretionary trading lives in your judgment in the moment; quantitative trading moves that judgment upstream into explicit rules and lets a machine execute them without flinching. That single shift — the decision made once, executed a thousand times — is why a systematic strategy is built in layers rather than written in one sitting. Get the layers in the wrong order and the whole thing stalls at "where do I even start."
This is the build sequence: four layers, one worked example carried through all of them, and the one decision each layer forces you to make.
Key Takeaways
Every systematic strategy is built in four connected layers — data pipeline, signal logic, execution, and the paper-to-live transition — not one big leap.
A hypothesis only becomes a system once it is written as unambiguous entry and exit rules a machine executes the same way every time.
Slippage, spread, and rejection live in the execution layer — your real edge is what survives them, not the frictionless backtest.
Flip to real capital on a deliberate go/no-go decision with thresholds you set in advance, never on a vague 'it feels ready.'
Table of Contents (16 min read)Contents
The Four Layers Every Systematic Strategy Needs
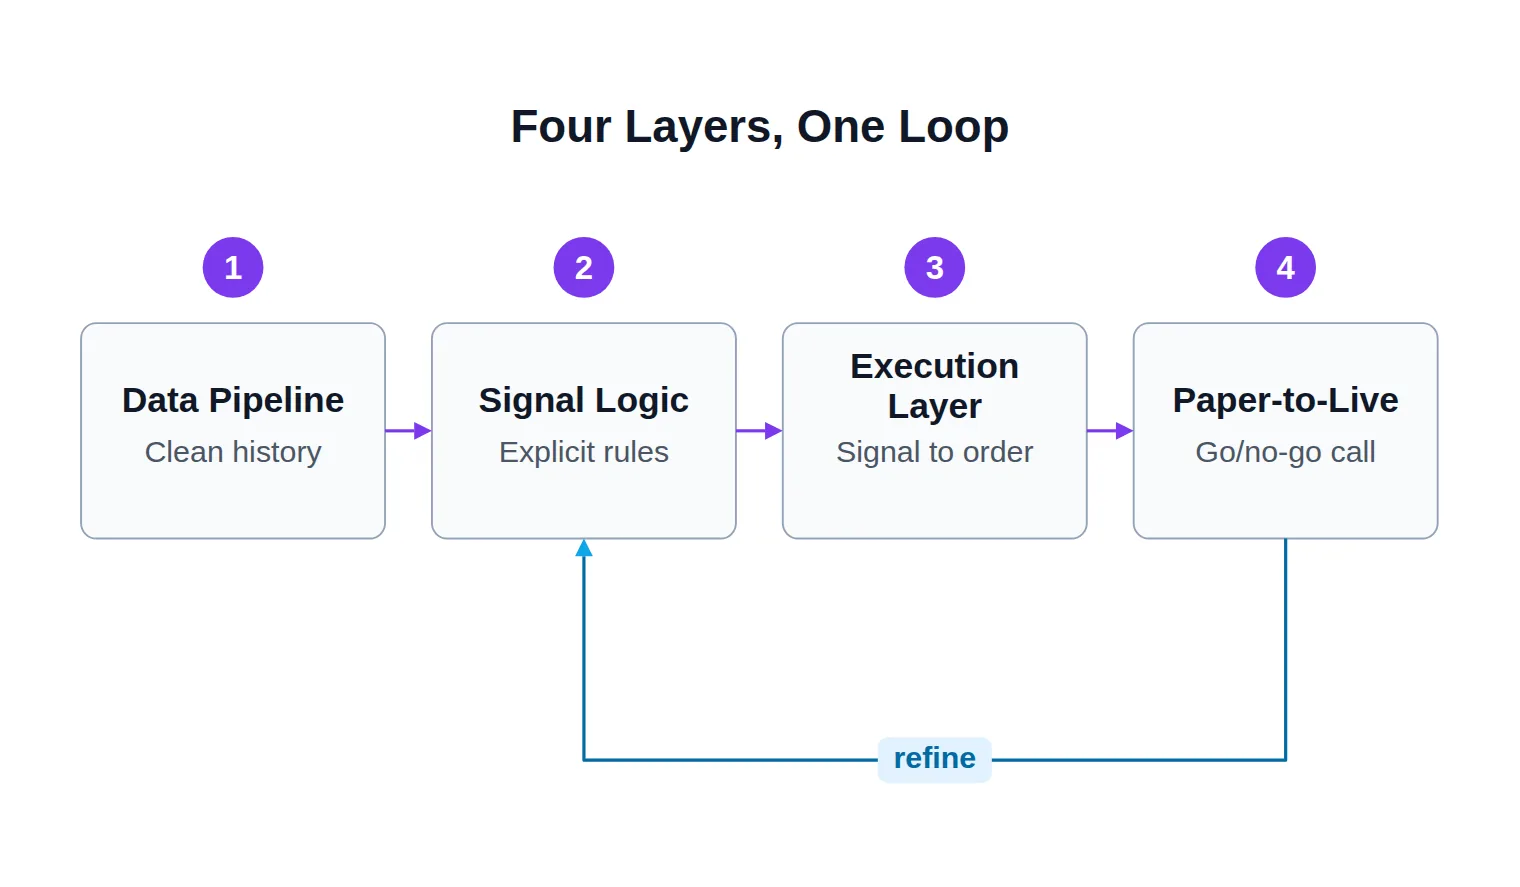
Think of a systematic trading strategy as a pipeline, not a formula. Data flows in, a rule turns it into a signal, the signal becomes an order, and the result flows back to tell you whether the rule was any good. Four layers, in a fixed order:
Data pipeline — the raw material: clean price history the rest of the system can trust.
Signal logic — the rule set that turns that data into a buy, sell, or stay-flat decision.
Execution layer — the plumbing that turns a decision into a real order at a broker or exchange.
Paper-to-live transition — the deliberate go/no-go call before real money is on the line.
Each layer feeds the next, and the whole thing loops: what you learn running the system flows back into refining the rules. Miss a layer and the system either cannot be tested (no data), cannot act (no execution), or blows up on contact with a live market (no transition discipline).
The four layers connect in a fixed order, and what you learn running the system loops back into the signal logic.
People swap the terms algorithmic trading and quantitative trading almost interchangeably, and for a build like this the distinction is small: quant is the research that finds an edge, algorithmic execution is the code that trades it. You need both — which is why this sequence runs from data all the way to a live order.
To keep it concrete, we will build one deliberately simple strategy across all four layers: a moving-average crossover — go long when a fast average crosses above a slow one, exit when it crosses back. It is not a strategy to trade as-is; it is the smallest complete example that touches every layer, so the wiring stays visible.
Layer 1 — Building a Data Pipeline You Can Trust
Every downstream layer inherits the quality of your data. A rule tested on messy prices produces a mirage — a result that looks brilliant because it traded on ticks that never really printed. So the first build step is not strategy at all; it is a data pipeline you can trust.
Three jobs live here:
Sourcing — where the price history comes from: a broker or exchange API, a data vendor, or an exchange's historical dump. For our crossover you need clean daily or hourly OHLC (open-high-low-close) bars for one symbol, with enough history to cover several market regimes — not just the last calm quarter.
Cleaning — real data has gaps, duplicate timestamps, bad ticks, and splits or symbol changes. Decide how you fill a missing bar, how you treat a weekend gap, and whether you adjust for corporate actions. Whatever you decide, apply it identically in testing and live — a mismatch there is a silent killer.
Storage — keep the cleaned series somewhere both your backtest and your live bot read the exact same numbers. A flat file works to start; a small database earns its keep once you track several symbols and timeframes.
The decision this layer forces: which single data source and timeframe you standardize on. For the crossover, that might be "daily bars for one liquid symbol from source X, weekend gaps left as-is." Write it down — you will need to reproduce it exactly when you go live.
Layer 2 — Turning a Hypothesis Into Signal Logic
A hunch is not a strategy. "Momentum tends to continue" is a hypothesis; it becomes signal logic only when you can state, with zero ambiguity, exactly when the system enters, exactly when it exits, and what it does the rest of the time. If two people can read your rule and disagree about whether today is a buy, it is not a rule yet.
Our hypothesis: when a short-term average of price rises above a longer-term average, momentum is turning up. Written as logic, that is two boolean conditions on the data from Layer 1:
The rule, made explicit
pythonma_cross.py
# 20/50 simple moving-average crossover — one symbol, daily bars
fast = close.rolling(20).mean()
slow = close.rolling(50).mean()

# A "cross up": fast was at or below slow last bar, and is above it now
long_entry = (fast > slow) & (fast.shift(1) <= slow.shift(1))
long_exit  = (fast < slow) & (fast.shift(1) >= slow.shift(1))

position = 0
for i in range(len(close)):
    if long_entry[i] and position == 0:
        position = 1        # open long on the next bar's open
    elif long_exit[i] and position == 1:
        position = 0        # go flat
The hypothesis 'momentum is turning up' becomes two unambiguous boolean rules a machine runs the same way every time.
Notice what the code forces you to pin down that prose let you dodge: which averages (20 and 50 bars), what counts as a "cross" (the fast line was at or below the slow line last bar and is above it now), and what happens between signals (you hold, or you are flat). That precision is the entire point of the layer.
The trap here is overfitting — quietly tuning those numbers until the rule looks perfect on the history you are staring at. Twist 20 and 50 into 17 and 52 because they backtest a little nicer and you have stopped describing the market and started memorizing it; the edge evaporates the moment new data arrives. Keep the rule simple enough that it could plausibly work on data you have never seen.
The decision this layer forces: the exact rule format — every parameter, every condition, every tie-break — frozen before you test it, so the test measures the idea rather than your ability to curve-fit it.
Layer 3 — The Execution Layer: From Signal to Order
A signal that never becomes an order is a research project, not a trading system. The execution layer carries a decision from your rule engine to a live market and back — and it is where most first systems quietly break, because a backtest assumes a fill your broker may not give you.
When the crossover fires, something has to:
Translate the signal into an order — a market order for immediate entry, or a limit order to take only a specified price. Market orders fill fast but at whatever price is there; limit orders control price but may never fill.
Send it to the broker or exchange — over a direct API, a MT4/MT5 connector, or a webhook-driven bridge. This is where your rules meet a real account.
Manage the trade's life — confirm the fill, track the open position, and fire the exit order when the opposite cross prints.
sequenceDiagram
    autonumber
    participant Bot as Strategy Bot
    participant Broker as Broker API
    participant Engine as Matching Engine
    Note over Bot: Fast MA crosses above slow MA
    Bot->>Broker: Place market order
    Broker->>Engine: Route order
    Engine-->>Broker: Fill at market price
    Broker-->>Bot: Confirm fill and price
    Note over Bot,Broker: Realized price differs from signal price
Between the price your signal saw and the price your order gets sits slippage — and your live edge is whatever survives it.
The gap the diagram exposes is slippage: the price your signal saw and the price your order actually gets are rarely identical, and spread plus commission widen it further. A crossover that is marginally profitable in a frictionless backtest can be a net loser once real execution costs bite — which is exactly why the paper-trading step in Layer 4 exists.
How much you commit per trade belongs here too. Deciding your position sizing is what keeps one bad run from ending the account, and the execution layer is where that number becomes a real order quantity. Need the wiring for a specific platform? Our connector hub covers how a signal reaches an MT5 account across brokers and exchanges.
The decision this layer forces: which execution method — direct API, a connector, or a webhook bridge — and which order type your rules use. That choice decides how much slippage you inherit, and how much of your backtested edge actually reaches your account.
Where Backtesting Fits Into the Build Loop
Between writing the rule and trusting it with money sits the backtest — running your frozen Layer 2 logic over the Layer 1 history to see how it would have behaved. This article does not re-teach the full method — learning how to backtest a trading strategy is its own end-to-end discipline, and our dedicated guide walks that process start to finish. What matters for the build is where it plugs in and which engine style fits.
Two engine styles dominate, and the choice is a genuine fork in the road:
Vectorized vs Event-Driven Backtest Engines
Vectorized
Computes signals across the whole price series at once
Fast to write and fast to run — great for a first screen
Assumes clean fills, so it hides slippage and order queuing
Best for quickly screening whether an idea is worth deeper testing
VS
Event-Driven
Steps bar by bar, the way a live bot actually would
Models fills, latency, and partial executions
Slower and more code — but far closer to live reality
Best for the honest validation run before you risk capital
Screen ideas with a vectorized engine; validate the survivor with an event-driven one that models real fills.
Whichever you choose, the guardrail is the same: quarantine a slice of history the rule never touched during design and test on that — an out-of-sample test. A crossover that shines on the data you built it on but falls apart out-of-sample was overfit, full stop. A Monte Carlo simulation — reshuffling the trade sequence to see the range of outcomes rather than the single lucky path — tells you how fragile the result is before a live market does.
The decision this layer forces: which engine style matches how you will eventually run live, and how much untouched history you set aside for the honest test.
Layer 4 — Paper Trading to Live: How Do You Know You're Ready?
A clean backtest earns your strategy a paper trading run — also called forward testing — where the system trades live market data in real time but with no real money. It is the one test a backtest cannot fake: it exposes data-feed hiccups, latency, and execution quirks the historical run smoothed over. Skipping it is the single most common way a promising system meets an ugly surprise.
The mistake is not paper trading too little — it is flipping to real capital on a feeling. "It seems to be working" is not a decision; it is the absence of one. You need a deliberate go/no-go point defined before you start, so the choice to risk money rests on evidence, not on the mood of a good week.
Here is a concrete version of that gate for the crossover — adapt the numbers to your strategy's trade frequency, but decide them in advance:
Decide these thresholds before you start
Paper-to-Live Go/No-Go Checklist
0 / 6
Paper traded across a time window long enough to span more than one market condition — not just a single calm month
Reached a minimum trade count large enough that the results are not luck — many strategies need dozens of trades before the average means anything
Live paper results broadly match the backtest — an edge far below the tested one signals slippage or a flawed assumption
Passed an out-of-sample and a Monte Carlo check, so the edge holds on data and orderings the rule never saw
Every risk control — stop-loss, max open positions, a kill-switch — is coded and tested, not just planned
First live run is sized small: risk an amount you can lose without it changing how you trade
★
Checklist complete — you’re cleared to proceed.
Clear every box and you go live — small. Miss even one and you keep paper trading or send the rule back to Layer 2. Trading carries a real risk of loss; treat the first live run as the most expensive part of the test, not the finish line. Read our risk warning before committing capital.
The decision this layer forces: the honest go/no-go call — go live at reduced size, or loop back — made against thresholds you set while you were still calm.
Where Risk Controls and Performance Metrics Attach
A running system is not a finished one. Two things attach to the strategy you have just built, and each is deep enough to own its own guide.
Risk controls wrap the whole pipeline. Stop-losses, a cap on open positions, correlation limits, and a kill-switch that halts everything when something goes wrong are what stand between a losing streak and a blown account. Deciding how much to lose before the system stops is risk management for an automated strategy — a discipline in its own right, covered in its own dedicated guide, and it is not optional: the crossover's raw logic says nothing about it on its own.
Most first systems fail in predictable ways. Watch for these:
Curve-fitting the rule to the past. If you tuned parameters until the backtest sparkled, you optimized for history, not the future. Simpler rules survive longer.
Ignoring costs. A strategy that is profitable before spread, commission, and slippage and unprofitable after them is unprofitable. Model costs from the start.
Testing and trading on different data. If your live feed cleans gaps differently than your backtest did, you are trading a different system than the one you validated.
No out-of-sample discipline. A result never checked on untouched data is a hypothesis wearing a lab coat.
Going live too big, too soon. The first live run is diagnostic — size it so a bad surprise is a lesson, not a wound.
Building without a kill-switch. Automation compounds mistakes as fast as it compounds edges; you need a way to stop it instantly.
Next Steps
You started with a hunch and no wiring diagram. Now you have one: data you can trust, a rule precise enough to code, execution that survives contact with a real market, and a go/no-go gate that keeps emotion out of the moment money goes on the line.
Pick your simplest real idea and take it through the four layers this week — one symbol, one timeframe, one rule frozen before you test it. The crossover was never the point; the sequence is. Build the smallest complete version, watch where it breaks, and let that feed back into the next version. That loop — build, test, learn, refine — is what quantitative trading actually is once the mystique wears off.
FAQ
Do I need to know how to code to build a quant strategy?
You need enough to express a rule unambiguously and connect it to a broker — not a computer-science degree. The signal logic for something like a crossover is a handful of conditions, and many platforms let you script rules in an accessible language. The harder skill is not coding; it is defining the rule precisely enough that code becomes possible.
How much historical data is enough to test a strategy?
Enough to cover several different market conditions — trending, ranging, and volatile — not just the recent stretch that happens to suit your idea. A rule that only ever saw a calm uptrend has not been tested; it has been flattered. The right span depends on your timeframe, but "more regimes" beats "more years of the same regime."
How long should I paper trade before going live?
Long enough to accumulate a meaningful number of trades across more than one market mood, and long enough for live execution quirks to surface. A high-frequency rule reaches that in weeks; a slow one may need months. Decide the minimum trade count and time window in advance so the finish line is not a moving target.
Is a moving-average crossover a good strategy to start with?
As a learning vehicle, yes — it is the smallest strategy that touches all four build layers, which is why we used it here. As something to trade real money on unchanged, no: it is well-known, easily whipsawed in ranging markets, and offers no edge on its own. Use it to learn the pipeline, then build something with a real hypothesis behind it.
What's the difference between quantitative and algorithmic trading?
They overlap so much the words get swapped. The useful distinction: quantitative trading is the research — finding and validating an edge with data — while algorithmic trading is the execution — the code that trades that edge automatically. A complete system does both, which is why this build sequence runs from a data-driven hypothesis all the way to a live order.
Sources & Further Reading
Want to go deeper? These independent, authoritative sources shaped this guide — each one is worth reading in full:
The Cross-Market Desk is the SignalBots editorial team for topics that span every market — platform connectors, copy trading, partnership and IB programs, and the general mechanics of trading automation. We research and write the guides that apply no matter what you trade.

Discussions 0
Leave a comment