Your Strategy Tester report says the equity curve barely dips. Profit factor north of two, a drawdown you could sleep through, and a trade list full of clean order-block entries that ran to target. You wrote the logic yourself, so you know the rules are sound — and that is exactly why the number bothers you.
It should. ICT and Smart Money Concepts began as something a human read off a chart after price had already moved, and hindsight has a way of surviving the trip into MQL5. A confirmation rule that felt obvious while you were scrolling can quietly resolve one bar too early in code. A cost assumption that is fine for a swing system is badly wrong for entries that all land inside the London and New York opens. And a strategy that fires a handful of times a month can produce a report card that is mostly luck wearing a suit.
This is the validation pass. How to configure the MT5 tester for a pattern-confirmation expert advisor, how to catch the look-ahead leak that generic backtesting checklists cannot see, how to price the spread your entries actually pay, and how to read the report afterwards without flattering yourself. It assumes the code already exists — if you are still turning chart rules into MQL5, the full ICT automation build comes first.
Key Takeaways
Smart Money entry rules are claims about a sequence, so the bar where a pattern exists and the bar where your EA could have known it are different — sharing one index in code is the look-ahead bug that inflates most ICT backtests.
Run the verdict test on real ticks, not generated ones: an invented intrabar path is exactly the data a sweep-and-close or displacement rule depends on.
MT5 has no spread field — the tester takes spread from history — so anchor cost to the sessions you actually trade via real ticks, a per-lot commission margin, or a spread filter coded into the EA.
Judge the stitched out-of-sample record on profit factor, drawdown depth and duration, and expectancy in R. Net profit scales with lot size and ranks nothing.
Table of Contents (27 min read)Contents
Why Smart Money EAs Break Backtests Other EAs Survive
A moving-average crossover has a decision rule that is either true or false at a single instant. Fast line above slow line. Nothing in that sentence requires knowing what happens next, so transcribing it into code rarely introduces a time bug.
Smart Money entry rules are different in kind. Almost every one of them is a claim about a sequence that is only complete after price has already moved:
An order block is the candle before an impulse — and the impulse is the half that arrives later.
A fair value gap between candle one and candle three is not a gap until candle three prints.
A liquidity sweep is a wick beyond a level plus a close back inside; the close is the second condition.
A market structure shift is built on swing points, and a swing point needs bars on both sides of it.
None of that is a flaw in the strategy. It is a flaw waiting to happen in the code, because every one of those definitions contains two distinct moments: the bar at which the pattern exists, and the later bar at which your EA could have known it exists. If those two moments share an index in your source, your backtest is trading on information it did not have.
A backtest curve renders your assumptions. Change the assumptions and the same code tells a different story.
Three consequences follow, and all three are specific to this family of strategies. Confirmation timing is fragile, so look-ahead bugs are easy to write and nearly invisible to read. Entries cluster into the same one- or two-hour windows every day, so a flat cost assumption misprices the entire trade population in one direction. And the filters that make the strategy selective also make it infrequent, so the sample you are judging is thin.
Worth saying once, plainly: everything below tests whether your result is trustworthy, not whether your strategy is good. A rigorous backtest of a bad idea returns an honest negative number, and that is a useful outcome.
Set Up the MT5 Strategy Tester Correctly First
Every check further down assumes the base run is honest. If the tester is feeding your EA an invented price path or a fantasy cost model, a walk-forward split just gives you two flavours of the same fiction. Get the Strategy Tester settings right before you run anything you intend to believe.
Tick modelling: what each mode invents
The single most consequential setting on the page. MetaTrader 5 does not simulate a market — it replays one, and the modelling mode decides how much of that replay is real.
Modelling modes
Modelling mode
What it feeds your EA
Where it misleads an SMC EA
Use it for
Every tick based on real ticks
Real bid/ask ticks your broker recorded, spread included
It doesn't — but it only reaches back as far as the broker's tick archive
The verdict run
Every tick
A path interpolated between each minute bar's four prices
Invents the intrabar sequence, so a sweep-and-reverse can appear or vanish
Nothing you intend to act on
1 minute OHLC
Four control points per minute bar
Coarser invention still, plus stop and target fills that never happened
Rough first-pass parameter sweeps
Open prices only
One OnTick call, at each bar open
Honest for bar-close logic, but intrabar stop and target fills are fictional
Fast sanity runs and the peek test below
Math calculations
No price series at all
Irrelevant to a price-pattern EA
Non-trading optimisation maths
The four prices of each minute bar are real in every mode. Everything between them is real only in the real-ticks mode.
For a crossover EA the invented path is harmless — the crossover happens at the close either way. For an EA that decides whether a wick took out a level and then closed back inside it, the invented path is the signal. Generated ticks can manufacture a sweep that never happened, or smooth away one that did, and your trade list changes accordingly. Your verdict run uses real ticks. Everything else is a screening tool.
The rest of the setup page, briefly and without ceremony:
Execution delay — set it to Random delay, not No delay. Zero-latency fills are not a thing you will ever experience.
Commission — enter a real per-lot figure for the account type you will actually trade. It is also the only lever you have for adding cost by hand, which matters in the spread section below.
Account model — hedging or netting, whichever your live account is. If your EA can hold two positions on one symbol, a netting test quietly rewrites its behaviour.
Deposit and leverage — the deposit you will genuinely fund and the leverage you will genuinely get, so margin rejections show up in the test instead of on your first live signal.
A date range that spans more than one market regime
A Smart Money EA encodes a claim about how liquidity behaves. The only way to find out whether the claim holds generally is to test it across stretches where liquidity behaved differently.
Pull the range back until it contains, at minimum: a sustained trend, a long directionless chop, at least one volatility shock, at least one central-bank cycle turn, and at least one thin summer. That usually means several years, not several months — and it means resisting the urge to start the range on a date that happens to flatter the curve.
When performance turns ugly in one stretch, do not delete the stretch. Ask which of two things it is. If the EA should have recognised those conditions and stood aside, that is a missing filter and a genuine improvement. If it is simply a period the strategy loses in, that is information about your future drawdowns, and you want it in the record.
One practical constraint: broker tick archives are finite, and yours may not reach as far back as you want. Split the job rather than compromise it — real ticks for the recent block that decides, generated ticks for the older block that only screens. Just never let the screening block cast a vote.
Is Your EA's Order Block or FVG Confirmation Using Future Data?
Here is the question that makes look-ahead bias tractable. For every entry your EA takes, ask: at the instant this order was sent, which bars had actually closed? Everything the code touched must belong to that set. That is the whole rule; the rest is knowing where it leaks.
Bar zero is the bar being built. In MQL5, index 0 of any series is the forming bar, live and in the tester alike. Reading it is not automatically a bug — reading it as if it were finished is. A comparison against bar 0's high, low or close, before that bar closes, is a decision made with a number that has not settled yet.
The defining candle is earlier than the confirming bar. Your detector finds a pattern and stores the index of the candle that defines it — the order block candle, the middle candle of the gap, the sweep candle. That index always sits earlier than the bar at which the pattern became knowable. If the entry logic then reuses the defining index to ask "was this valid yet?", you have leaked, and by exactly the number of bars the confirmation took. Store two indices: where the pattern sits, and when it became true.
Right-side confirmation windows are the big one. Any swing-point detector that requires N bars to the right cannot report a swing until N bars later, and every structure-based rule you built on top of those swings inherits the delay. If your detector sweeps the whole history in one pass and marks swings, a backtest marks them all before they were confirmable. The classic symptom: a beautiful tester curve and a live EA that never seems to see the same setups.
Higher-timeframe bar zero cuts both ways. Multi-timeframe confirmation reads a daily or 4-hour bar while the current one is still open. Code that treats that partial bar as a completed range is not looking ahead — it is looking at less than it thinks, and its live behaviour will differ from the test for the opposite reason. Both failures produce the same headline: the backtest disagrees with reality.
Indicator buffers are a leak you cannot see in the EA. If your detection lives in a custom indicator and the EA reads it through CopyBuffer, the indicator's full-history calculation can differ from its bar-by-bar calculation. Anything that redraws a past value is repainting, and repainted values have no business anywhere near an entry decision.
Look-ahead in practice
The same setup, two different decision timesEUR/USD15m
Two bars and most of the displacement separate the leaky entry from the earliest one the code could legitimately have taken.
A two-bar leak is enough to turn an ordinary edge into a report you would frame.
Two bars does not sound like much. On a strategy whose entire premise is entering before the obvious move, two bars is frequently the difference between a mediocre result and a spectacular one — which is precisely why the bug is so easy to fall in love with.
Four ways to catch a leak you cannot see in the code
Source review finds the obvious ones. These find the rest.
Audit every zero index. List every CopyRates/CopyBuffer call starting at 0, every [0] on a series array, every iHigh/iLow/iClose with shift 0. Justify each one out loud. Most will be legitimate current-price reads; the ones you cannot explain in a sentence are your candidates.
Run the truncated-history test. Test the identical EA over January–June, then over January–December. The trades falling inside January–June must be identical in both runs. If knowing about July changed what happened in March, something in the chain reads forward — and this catches indicator-level leaks that source review will not.
Diff the modelling modes. If your EA is bar-close-only, run Open prices only and Every tick based on real ticks over the same window. Fills, slippage and exact P&L will differ. The list of entry bars should not. A different set of entries means the logic is reacting to intrabar data it does not admit to using.
Single-step it in visual mode. Slow the tester down at three or four entries and confirm the arrow lands on the bar after the confirming bar closed, not on the confirming bar itself. Tedious, and it still catches bugs the other three miss.
Model Spread and Slippage the Way Killzones Actually Trade
If you came to MT5 from MT4, the first surprise is that there is no spread field to fill in. During testing the spread is not modelled at all — it is taken from historical data and always treated as floating. You cannot simply type in a pessimistic number.
That constraint bites this strategy family harder than most. Smart Money entries cluster into the session opens by design, and those are exactly the windows where the spread is widest, most volatile and least like the daily average. A flat average — which is what a generic backtesting guide will tell you to use — prices your trades at the cost of hours you never trade in. The stops make it worse: an SMC stop sits just beyond a wick by construction, the tightest placement the setup allows, so a few extra points of cost converts "missed by a hair" into "stopped out".
Three honest ways to handle it:
Use real ticks from the broker you will actually run on. The recorded bid/ask carries the real spread, including its session shape, so the cost model comes for free and is specific to your execution venue. A different broker will give you a different — equally valid — answer.
Turn extra spread into commission. The tester's commission settings are the one place you can add cost by hand. Convert a plausible extra spread at your entry times into a per-lot charge and set it there. It is blunt, a constant where reality is a curve, but it moves the result in the honest direction.
Build the guard into the EA and test with it switched on. A spread filter that refuses entries above a threshold, and a max-deviation limit on the order request, are live-trading features you want regardless. Once they are in the code, the backtest prices the trades you would actually have taken instead of the ones you wish you had.
Whatever trading session filter your EA uses, anchor the cost assumption to the same hours the filter allows. And leave execution delay on random rather than none, so slippage exists in the test at all.
Put the confirmation fix and the cost fix together and the report changes character. The figures below are illustrative — a worked contrast, not a real EA's results — but the direction and rough size of the move are what a corrected run typically looks like.
Worked contrast
Naive run — flattering by construction
Tick model: Every tick, generated from M1 bars
Spread: the broker's quiet-hours average, applied to every trade
Confirmation: setup evaluated on the defining candle
Window: one two-year block, optimised and reported on the same data
Illustrative figures, not a real EA's results. The lesson is the direction and magnitude of the change, not the numbers themselves.
Nothing in the strategy changed between these two columns. Only the assumptions the tester was fed.
The corrected column is not a worse strategy. It is the same strategy, measured properly — and it is the only one of the two you could have made a position-sizing decision from.
Walk-Forward and Out-of-Sample Validation, Step by Step
Optimisation is a search for the parameter set that best explains one specific past. Given enough inputs, something always fits — that is overfitting, and it is not a moral failing, it is what optimisers are built to do. The defence is structural: never judge a parameter set on the data that chose it.
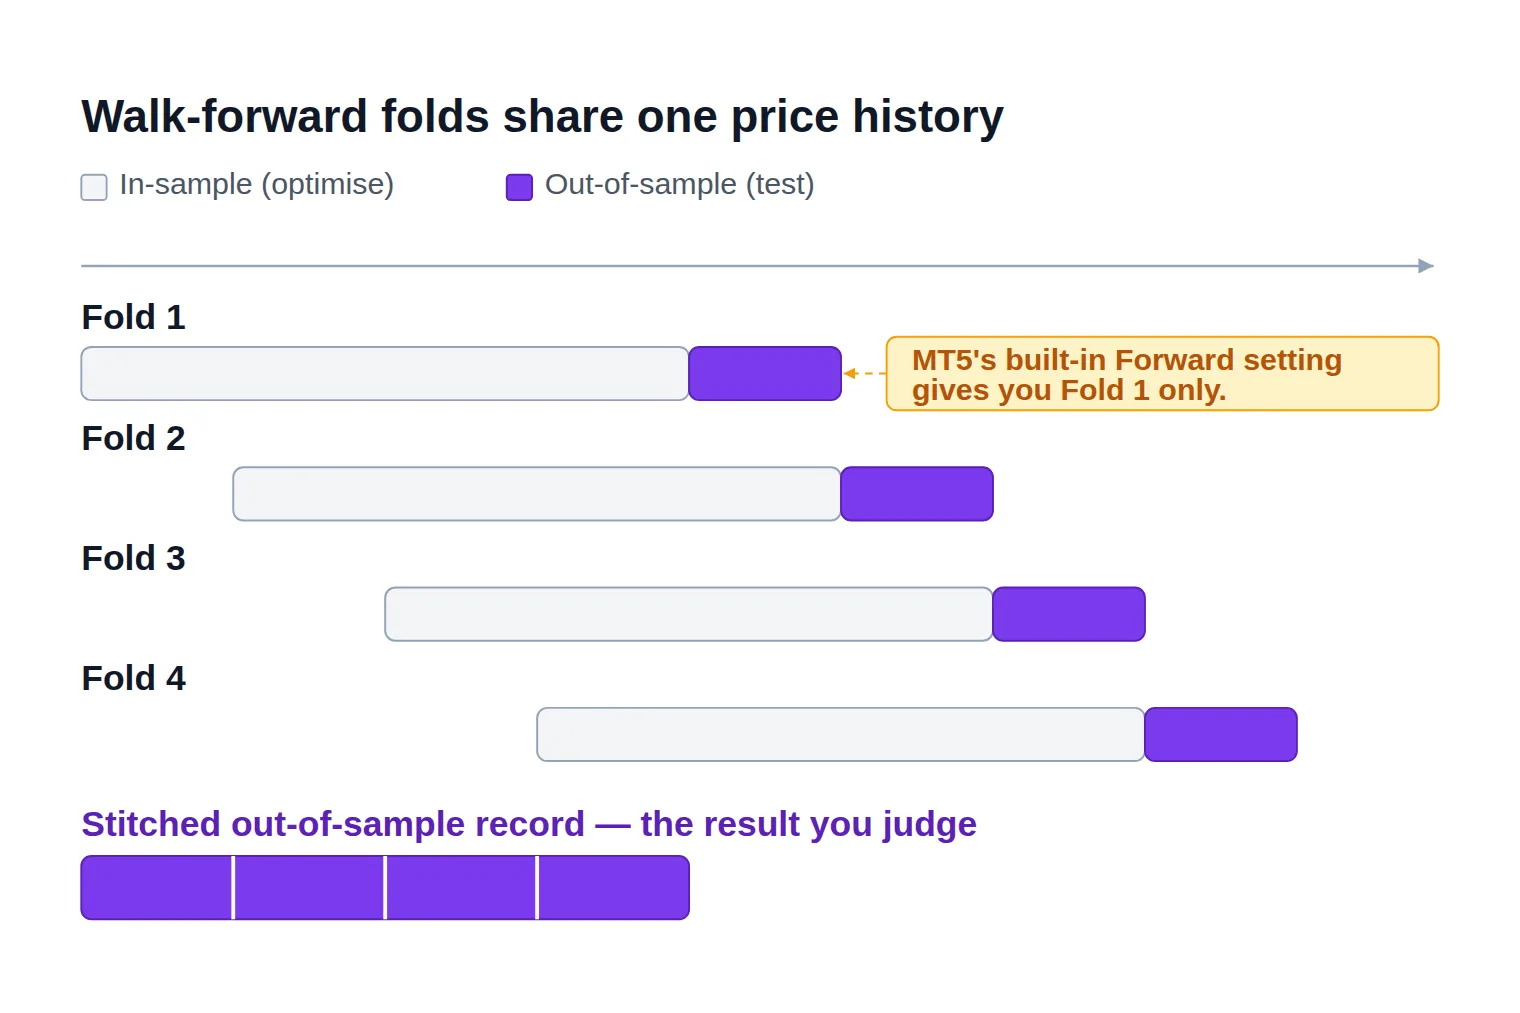
MT5 gives you the first half of that for free. The Forward setting on the tester's settings tab offers No, 1/2, 1/3, 1/4 or Custom. Choose a fraction and the tester optimises on the leading block, then automatically re-runs the best parameter sets on the trailing block it never optimised over, and reports the two side by side. That is genuine out-of-sample testing, and it is worth switching on every single time.
It is also exactly one fold. One fold answers "did this winner survive one unseen stretch?" — a real question, but a different one from "does this strategy survive being re-optimised repeatedly as conditions change?" For that you roll the windows yourself.
Each fold optimises on one block and is judged on the next; stitching the held-out blocks together is what stands in for a track record.
The manual procedure in MT5, which takes an afternoon and is worth every minute:
Choose a window pair. Something like twelve months in-sample, the following three months out-of-sample, is a reasonable starting shape for an intraday SMC EA. Longer in-sample if your trade count is thin.
Optimise on fold 1's in-sample block. Pick the winner by a robustness criterion — a balance-and-drawdown or custom criterion — never by maximum net profit.
Backtest that exact parameter set, unchanged, over fold 1's out-of-sample block. One run, no tuning. Record the trade list.
Slide both windows forward by the length of the test block, and repeat until you run out of history.
Stitch every out-of-sample block end to end. That stitched record — not any individual run, and certainly not the in-sample curve — is the closest thing you have to a paper trading history for this EA.
Then read the decay. Compare the stitched out-of-sample performance against the in-sample performance on the same metric; the ratio between them is your walk-forward efficiency. Some decay is normal and expected — a strategy that keeps everything out of sample is more likely to have a bug than an edge. As a working rule, surrendering more than half the edge suggests the parameters rather than the strategy were doing the work, and surrendering all of it is a verdict rather than a warning.
Two habits make the whole exercise more likely to pass honestly. Prefer a plateau to a spike on the optimisation surface: a parameter that works across a broad neighbouring range is describing something about the market, while one that only works at a single value is describing something about your sample. And keep the number of optimised inputs low — every additional degree of freedom buys the optimiser another way to memorise your history.
How Many Trades Do You Need Before You Trust the Result?
This is the question most backtest post-mortems skip, and it is the one that quietly invalidates the most Smart Money results. A selective strategy produces few trades. Few trades produce noisy statistics. Noisy statistics look exactly like an edge until they stop.
Run your own numbers rather than take a threshold on faith:
Sample-size check
Is your trade sample big enough to mean anything?
Enter what your backtest reported. The band shows how far the true win rate could plausibly sit from the one you measured, and whether your edge survives at the pessimistic end of it.
Closed trades in the test
Reported win rate
Average reward-to-risk achieved
Expectancy per trade
—
Win-rate uncertainty
—
Low end of the win-rate band
—
Expectancy at that low end
—
Halve the trade count and the uncertainty band widens by roughly 40%. Sample size is not a formality — it is most of the answer.
Drop the trade count to thirty and watch what happens: the band gets wide enough that a strategy reporting a comfortable win rate could plausibly be break-even. Push it into the hundreds and the band tightens until the measurement starts to mean something. That is the entire argument for a longer date range, in one interactive.
The trap for this strategy family is that every filter you add for quality costs you sample. A higher-timeframe order block, plus a session window, plus a sweep confirmation, plus a structure filter, can easily reduce an intraday EA to a few trades per month per symbol. Five years of history might yield a couple of hundred trades — enough to be suggestive, not enough to be conclusive, and nowhere near enough to justify six optimised parameters. If you tuned more than a handful of inputs on a sample that size, the optimiser had more freedom than the market gave it evidence.
Three legitimate ways to widen a thin sample size:
Test the same logic across more symbols with a comparable session profile, both individually and as a portfolio. Consistency across instruments is a robustness signal in its own right — and inconsistency tells you the edge was symbol-specific.
Extend the history, accepting that older blocks may only support generated ticks and therefore only screen rather than decide.
Reshuffle what you have. A Monte Carlo simulation over your existing trade sequence — same trades, different order, repeated a few thousand times — shows how much of your equity curve's shape was luck of sequencing. It is the single most useful thing you can do with a sample too small to extend.
What is not legitimate is loosening the filters to book more trades. That is not a bigger sample of your strategy. It is a small sample of a different one. And if you are unsure what reward-to-risk your EA actually achieved rather than targeted, our reward-to-risk calculator will turn a representative entry, stop and target into the ratio and the break-even win rate it implies.
The Metrics That Prove Robustness (and the One That Doesn't)
Net profit is the number everyone screenshots and the least informative figure on the page. It is a function of your deposit, your lot size, your leverage and whether you let the balance compound. Double the lots and it doubles, with no change whatsoever to the quality of the strategy. It ranks nothing and it proves nothing.
Here is the same illustrative EA's corrected run, read the way it should be read:
Report card
Reading the report card, in priority orderStitched out-of-sample record, illustrative example
Walk-forward efficiency
0.62
Profit factor (out-of-sample)
1.21
Max relative drawdown
26%
Longest drawdown duration
4 months
Recovery factor
2.1
Expectancy per trade
+0.18 R
Closed trades
148
Longest losing streak
9 trades
Average trades per month
2.5
Net profit
$8,430
Illustrative figures. Note that the headline everyone quotes — net profit — is the only line here that carries no verdict, because it cannot earn one.
Read them in this order:
Walk-forward efficiency first. How much of the in-sample edge survived on data the parameters never saw. If this is poor, nothing below it matters.
Profit factor, out-of-sample only. Gross profit over gross loss on the held-out record. An in-sample profit factor is a description of the optimiser's success, not the strategy's.
Maximum drawdown, relative and in percent — and its duration. Depth tells you what you would have risked; duration tells you whether you would have switched the EA off before it recovered. Most abandoned systems were abandoned during a normal drawdown. Our drawdown recovery calculator shows what gain each depth demands to get back to flat.
Recovery factor. Net profit divided by maximum drawdown — profit earned per unit of pain, and unlike net profit it is scale-independent.
Expectancy per trade, in R. The average outcome of one trade expressed in units of risk. It survives changes in lot size, which makes it comparable across tests and across strategies.
Longest losing streak, next to trades per month. Nine losses in a row at two and a half trades per month is nearly four months of nothing working. Knowing that number in advance is what keeps an EA switched on.
Win rate last, and never alone. Always read it beside average win versus average loss. A high win rate on a sub-1 reward-to-risk is not an edge; a modest one at 3R can be.
One more line worth a glance: modelling quality. When you run on real ticks it is not applicable, which is fine. When you run on generated ticks and it comes back low, the tester is telling you it had to invent more than usual — and on this strategy family, that is a reason to discard the run rather than caveat it.
A Pre-Launch Backtest Checklist for Your ICT EA
Everything above, condensed into things you can answer yes or no to. Work down it on your own EA before you let it touch a funded account.
Before you go live
Pre-launch backtest checklist for an ICT / Smart Money EA
0 / 12
Verdict run used 'Every tick based on real ticks', not generated ticks
Date range spans a trend, a chop, a volatility shock and at least one thin summer
Execution delay is set to random, not none, and commission reflects your real account
Every zero-index price and buffer read in the source is justified out loud
The truncated-history test reproduces identical trades in the overlapping period
Entry-bar list is unchanged between 'Open prices only' and real-ticks runs
Spread cost is anchored to the sessions the EA actually trades, not a daily average
Parameters were chosen on an in-sample block and judged on a held-out block
Out-of-sample blocks are stitched into one record and read as the real result
Trade count is large enough that the win-rate band still leaves expectancy positive
Longest losing streak and drawdown duration are numbers you can live with
Strategy was judged on profit factor, drawdown and expectancy — not net profit
★
Checklist complete — you’re cleared to proceed.
Any unticked box is a reason the number on your report is not yet a number you can act on.
The checklist ends where forward testing begins. Run the EA on demo with the same broker, the same VPS, the same symbol and the same hours you intend to trade, then compare that live trade list against a backtest over the identical dates. Same signals, same bars, similar fills means your model of the world matches the world. Any systematic divergence is your remaining bug, and it is far cheaper to find it there. That forward test is the last gate, not an optional extra.
If you would rather validate someone else's work than your own, exactly the same questions decide it. Ask any list of EAs ranked by backtested win rate which tick model produced the number, what the spread assumption was, and whether the reported result came from a held-out window or the one the parameters were fitted on. A vendor who can answer all three is worth listening to.
Before You Trust It With Money
The report you started with — the one with the smooth curve and the suspiciously clean order-block entries — was never lying. It was answering the question you asked it, using the assumptions you gave it. Change the tick model, the confirmation bar, the cost anchor and the window, and it answers a harder question honestly.
That harder answer is almost always smaller, and it is the only one you can size a position from. A Smart Money EA that survives real ticks, a corrected confirmation bar, killzone-anchored costs, a rolling out-of-sample split and a sample large enough to mean something has earned a demo account. Nothing less has.
FAQ
Can I trust a backtest run with generated ticks at all?
For screening, yes. Generated ticks are fine for narrowing a wide parameter range or checking that the EA runs without errors. They are not fine for the run you make a decision from, because the intrabar path they invent is exactly the data a sweep-and-close or displacement rule depends on. Screen with generated ticks; decide on real ones.
How long should the backtest period be for an ICT EA?
Long enough to contain several distinct market regimes and enough trades that the win-rate band is narrow, which for a selective intraday strategy usually means years rather than months. Let the trade count and the regime coverage set the length, not a round number. If your broker's tick archive is shorter than the range you need, use real ticks for the decisive recent block and treat the older block as screening only.
What is the fastest way to tell if my EA is repainting?
Run the truncated-history test. Test the EA to the end of June, then test it again to the end of December, and compare the trades inside the overlapping January-to-June window. They must be identical. If the longer run produces different trades in the same period, something in the EA or its indicators is using information from bars that had not printed yet.
Does the MT5 Forward setting count as walk-forward analysis?
It is genuine out-of-sample validation, and it is one fold rather than a rolling analysis. The tester optimises on the leading block and re-runs the winners on the trailing block automatically, which answers whether the chosen parameters survived one unseen stretch. Rolling the windows repeatedly and stitching the out-of-sample blocks together answers the broader question of whether the strategy survives periodic re-optimisation.
How do I add a wider killzone spread to an MT5 backtest?
You cannot type a spread into the MT5 tester — it takes the spread from historical data and treats it as floating. The three practical routes are running on your own broker's real tick history so the recorded spread carries its real session shape, adding a per-lot commission as a deliberate pessimism margin, or coding a spread filter into the EA and testing with it enabled so only trades you would genuinely have taken get counted.
Is a very high win rate in a Smart Money backtest ever real?
It can be, on a strategy that takes small profits relative to its risk — a high win rate at a sub-1 reward-to-risk is arithmetically ordinary. What should raise your eyebrows is a high win rate combined with a high reward-to-risk and a shallow drawdown, on a strategy whose entry rules depend on pattern confirmation. That combination is the signature of a look-ahead leak far more often than it is the signature of an edge.
Should I optimise on real ticks or generated ticks?
Optimise on generated ticks if you must — optimisation runs thousands of passes and real ticks are dramatically slower — but validate every surviving candidate on real ticks before it goes any further. A parameter set that only looks good under generated ticks is telling you it depends on an intrabar path the tester invented.
Sources & Further Reading
Want to go deeper? These independent, authoritative sources shaped this guide — each one is worth reading in full:
The Cross-Market Desk is the SignalBots editorial team for topics that span every market — platform connectors, copy trading, partnership and IB programs, and the general mechanics of trading automation. We research and write the guides that apply no matter what you trade.

Discussions 0
Leave a comment